Published • loading... • Updated
HBF for High-Throughput LLM Serving (UC Berkeley, FuriosaAI)
Summary by Semiconductor Engineering
 This story is only covered by news sources that have yet to be evaluated by the independent media monitoring agencies we use to assess the quality and reliability of news outlets on our platform. Learn more here.
1 Articles
1 Articles

HBF for High-Throughput LLM Serving (UC Berkeley, FuriosaAI)
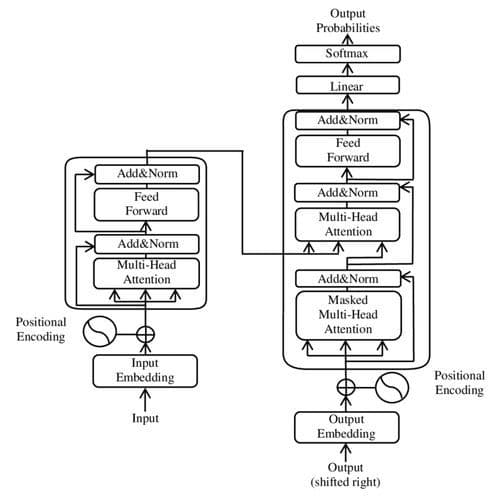
Researchers at the UC Berkeley and FuriosaAI published a technical paper titled “Characterizing High Bandwidth Flash for LLM Serving.” Abstract: “Large language model (LLM) serving requires substantial memory to store model weights and KV caches. As models grow larger and contexts become longer, memory capacity and bandwidth increasingly become bottlenecks for serving performance. Agentic workloads... »
Coverage Details
Total News Sources1
Leaning Left0Leaning Right0Center0Last UpdatedBias DistributionNo sources with tracked biases.
Bias Distribution
- There is no tracked Bias information for the sources covering this story.

Factuality
To view factuality data please Upgrade to Premium